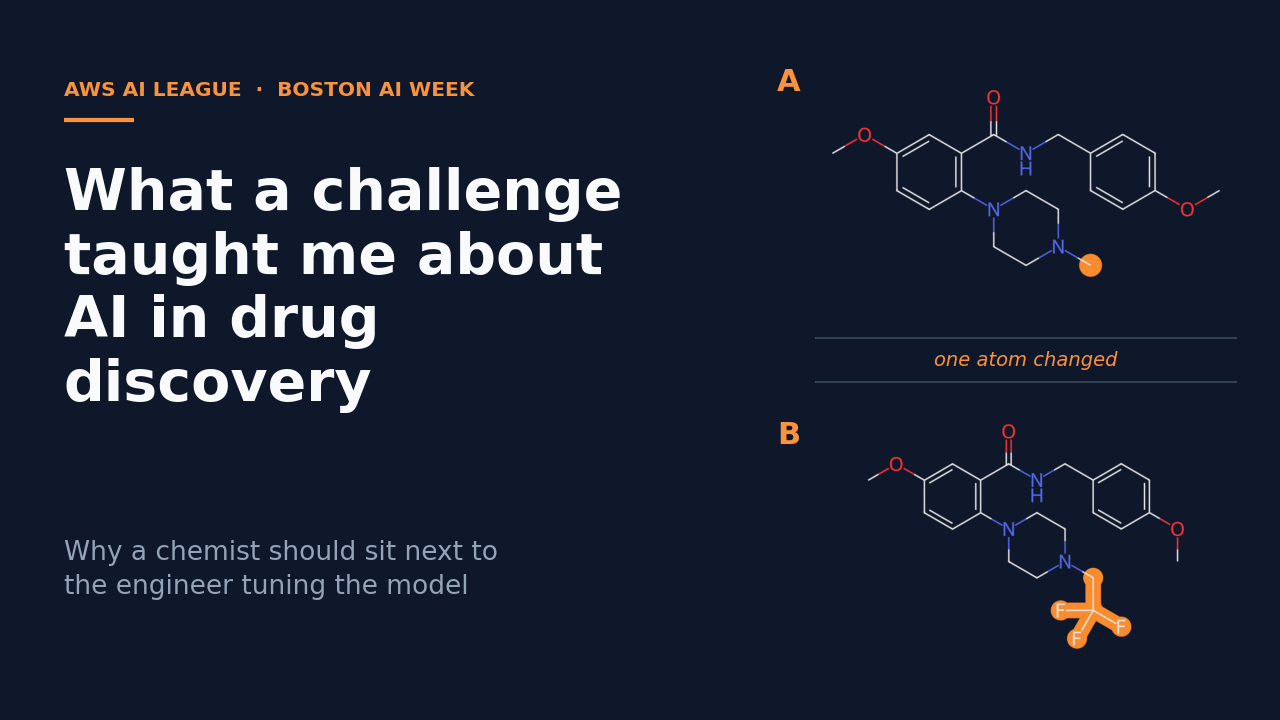
I spent a Friday last week at the AWS AI League drug discovery challenge in Boston, and for a very short while I was first on the leaderboard. I finished outside the prizes, and the reason taught me a lot. It was an eye opener for AI use in drug discovery and development.
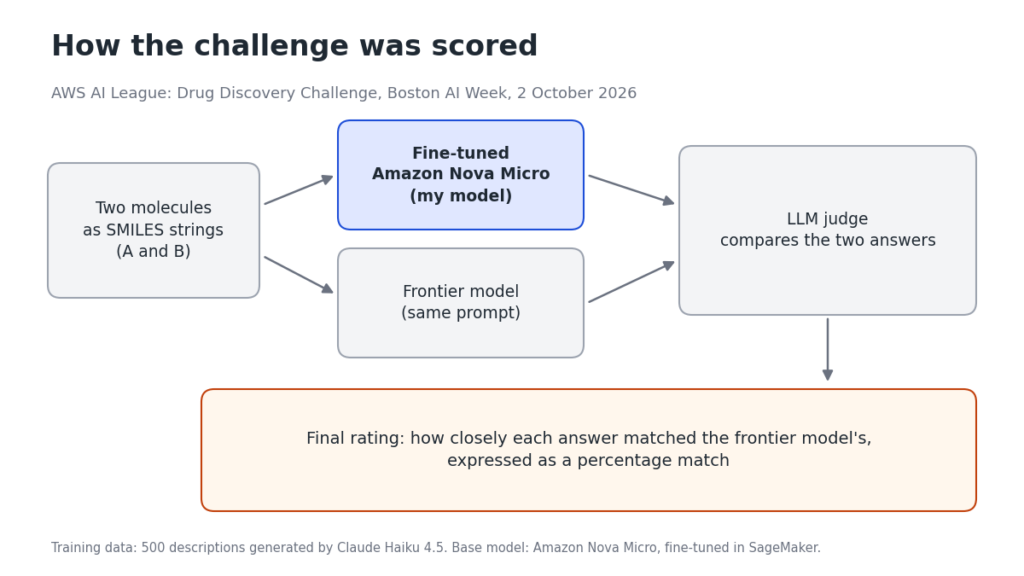
The task: fine-tune Amazon’s small Nova Micro model so that, given two molecules as SMILES strings, it describes how they differ in structure and what that means for permeability and efflux. We got 500 example descriptions written by Claude Haiku 4.5.
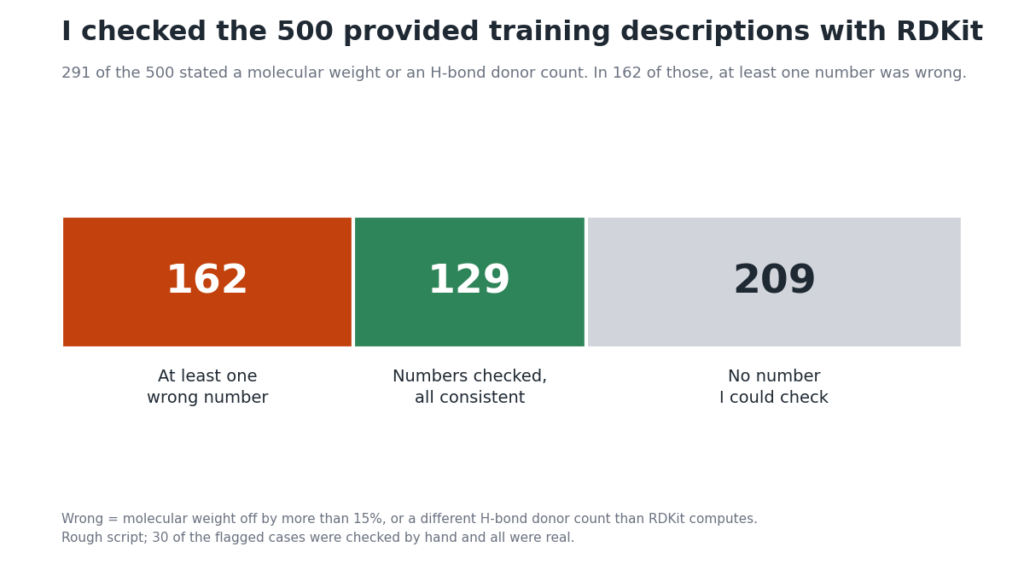
I trained on them as provided and submitted. That baseline took first place, though only three teams were on the board at that point. Then I checked the training data with RDKit. Of the 500 descriptions, 291 stated a molecular weight or a hydrogen-bond donor count, and 162 of those had at least one number wrong. One gave a molecule a donor it does not have. I rebuilt the descriptions from computed values and retrained. The score did not improve.
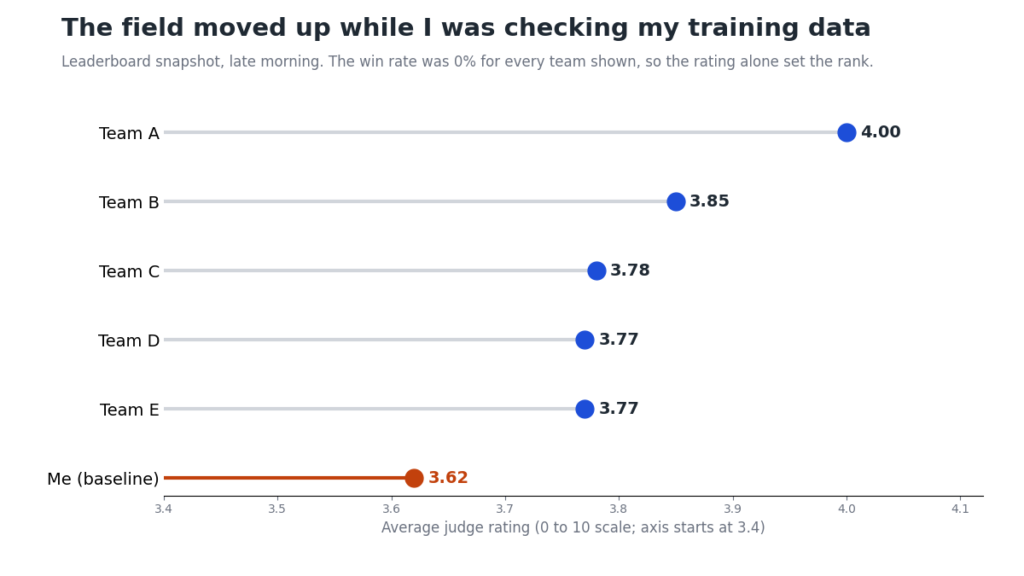
I only worked out how the scoring worked after spending most of the morning on data quality. In the end, every team was rated on how closely its answers matched a large frontier model’s answers to the same prompts, roughly a percentage match. The contest rewarded an output that was similar to the output from the frontier model, which is not the same as being right about the molecule.
The top teams saw that sooner. As I understood their pitches, the winner fed the first model’s outputs back in so each round landed closer to the frontier model’s answers. Second place kept tuning the training parameters until the numbers moved. Third brought in an outside dataset. All three are sound engineering against the metric that was set.
I am not complaining. The rules were published, and it showed me something I see often. People who optimize models follow the number in front of them, and many are not chemists or life scientists. They chase data, they develop models. They iterate. That is useful, because they get results I would not. I was thinking too much like a scientist rather than an engineer. It also meant that the answers we were training toward could be fluent and, in a lot of cases, wrong about basic science, and nothing in the score would flag it.
I have been using AI tools from Google, Anthropic and now AWS, sitting on the same table with them, and with their guidance using AI for chemical structure, property prediction, drug discovery, target identification and these companies are good at it. They are better when a chemist or life scientist is positioned next to the AI engineer as they work through each problem – the “human in the loop” who checks, iterates, optimizes the output AND focuses the tools to solve the problem. We certainly need AI and machine learning in drug discovery and development, but we also need to optimize for the problem, not just the numbers and the volume of output.
Thanks to AWS and Boston AI Week for running it.